LLM Development for Grounded Answers

Myth Digital is software and AI development agency based in Belfast and London. Our team builds production AI assistants that are tailored to answer from your documents and data, removing the guess work. Using RAG (retrieval-augmented generation) to retrieve, cite and score every response, and deploying outputs securely.

  • Answers grounded in your data
  • Cited sources, confidence scores
  • Private UK hosting
300+ Projects delivered to market
2 offices Belfast and London
10+ yrs Average years of experience in the team
Myth Digital team at work in the studio visible in the interface

LLM development is the engineering that makes a AI work reliably with your data, your rules and your existing systems. Most businesses don't need to train a model from scratch.

It covers model selection, data pipelines, retrieval layers, prompt engineering, evaluation and secure deployment. The goal is a production service that answers from your content with focused. We ingest your documents, build the retrieval index, write and test prompts, then deploy a system your team can trust. Confidence scoring measures flags uncertain answers for human review. Nothing slips through unchecked. That's how an off-the-shelf model becomes a reliable part of your operations. If you already have documents, policies or records that staff search manually, you likely have a strong starting point. Read more about our AI development services or get in touch to talk through your data.
AlphaVictor
Bushmills
Coca-Cola
Complieye
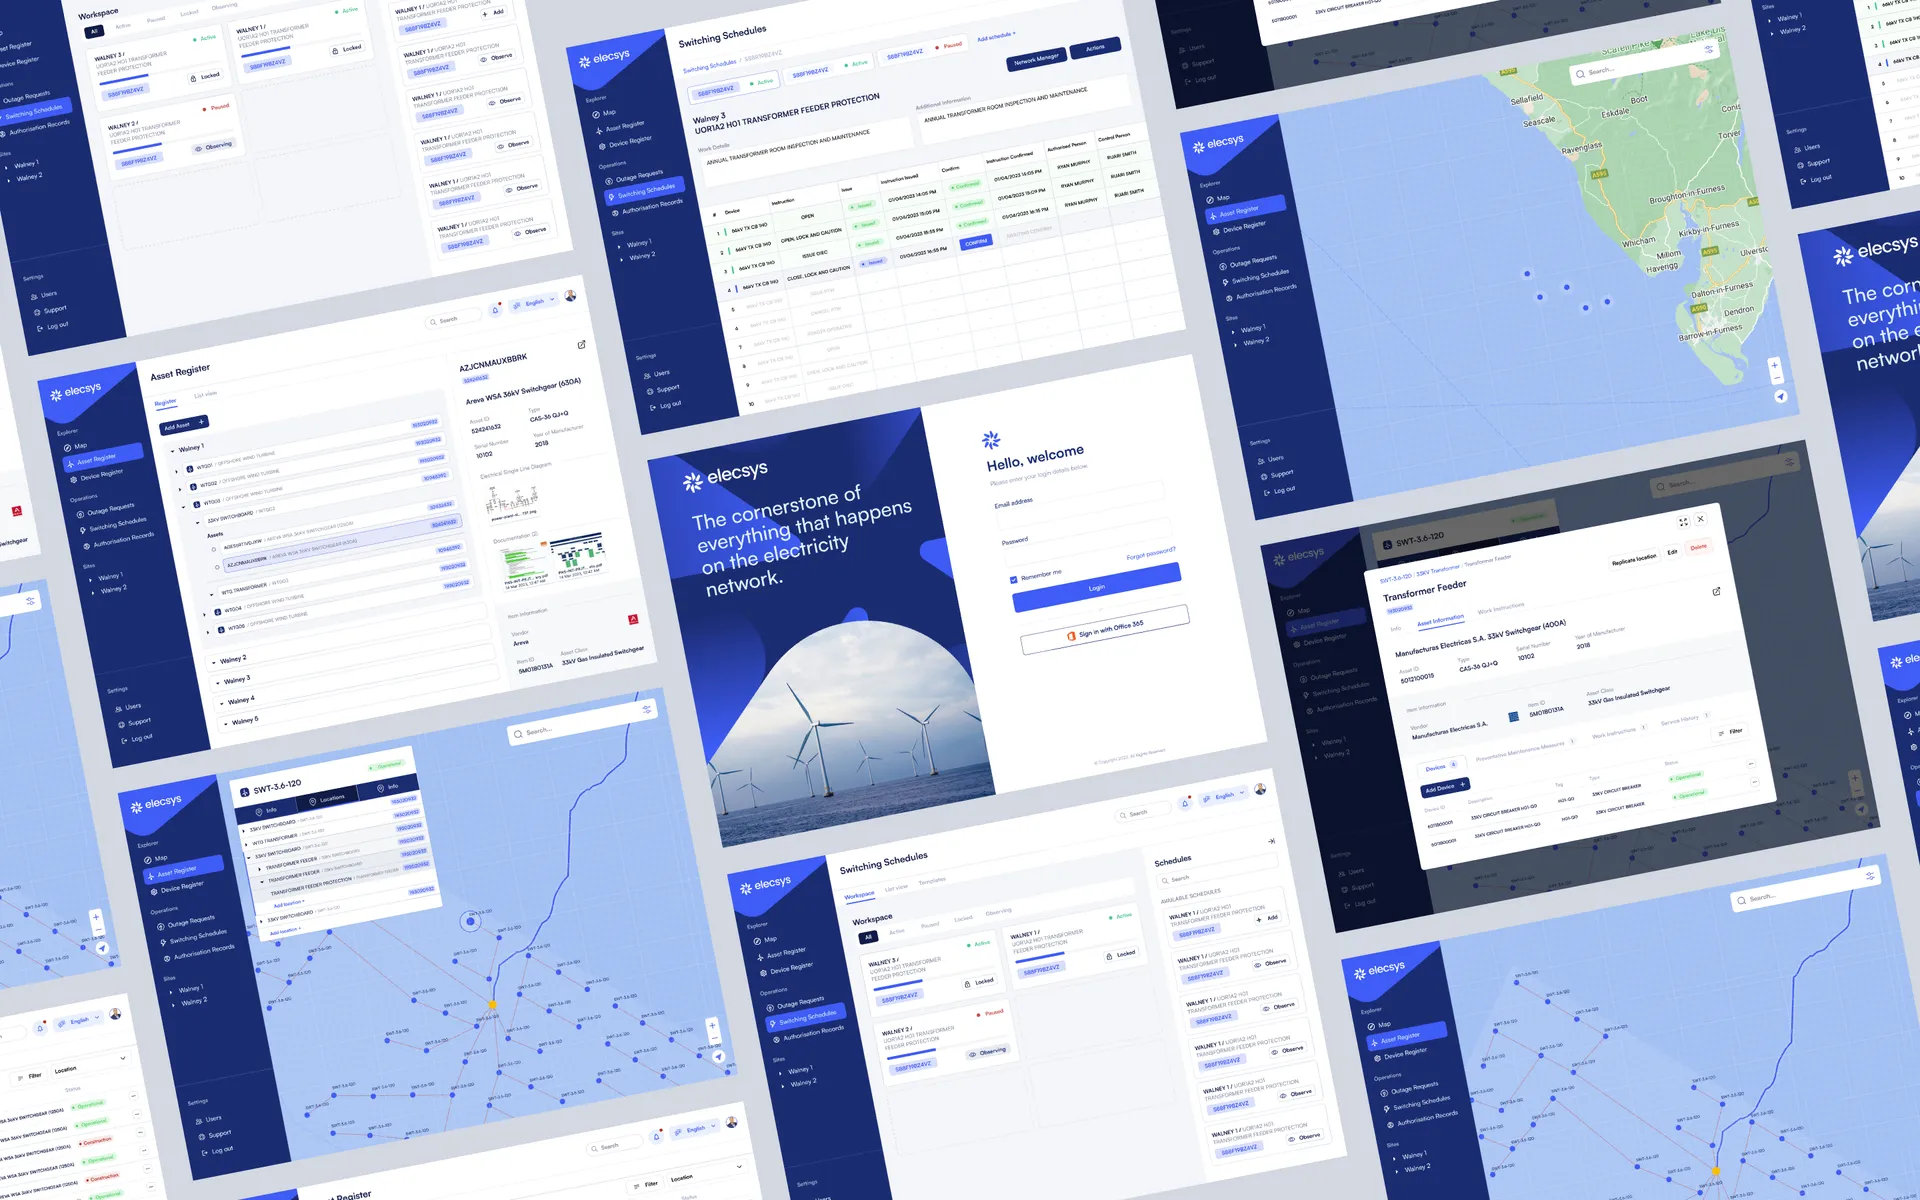
Elecsys
Glen Dimplex
LifePass
The Lir
NHS
The North Face
Perks
Queen's University
Deep RiverRock
SPAR

What we build for you

  • Retrieval-augmented generation

    Answers from your documents

    We index your approved content so the model answers only from sources you control. Every response traces back to the original document. Your team has full visibility over what the assistant says and why.

  • Grounding & hallucination control

    Citations, not guesswork

    Every answer carries mandatory citations and a confidence threshold. Low-confidence outputs route to a human for review, so nothing unverified reaches your users.

  • Private, UK-hosted deployment

    Your data stays yours

    UK-region cloud hosting with encryption, VPC isolation and strict access controls from day one. We set this up at the start to meet data-residency and compliance requirements. No retrofitting later.

Screen from the QualiT case study

RAG or Fine-Tuning: Which Fits?

We usually start with retrieval-augmented generation (RAG). It searches your documents at query time, returns cited answers and stays current without retraining. Fine-tuning suits cases where you need to change model behaviour at large scale. Start with RAG. Add fine-tuning only if evidence supports it.

  • RAG deploys faster and costs less to maintain
  • Every answer traces back to a source document
  • Fine-tuning wins for consistent style at volume
  • We scope the right approach in a feasibility call

How do we prevent LLM hallucinations?

Fabricated answers erode trust fast. We layer five tested techniques so your assistant only returns grounded, quality, verifiable responses your team can act on.

Source Restriction via RAG
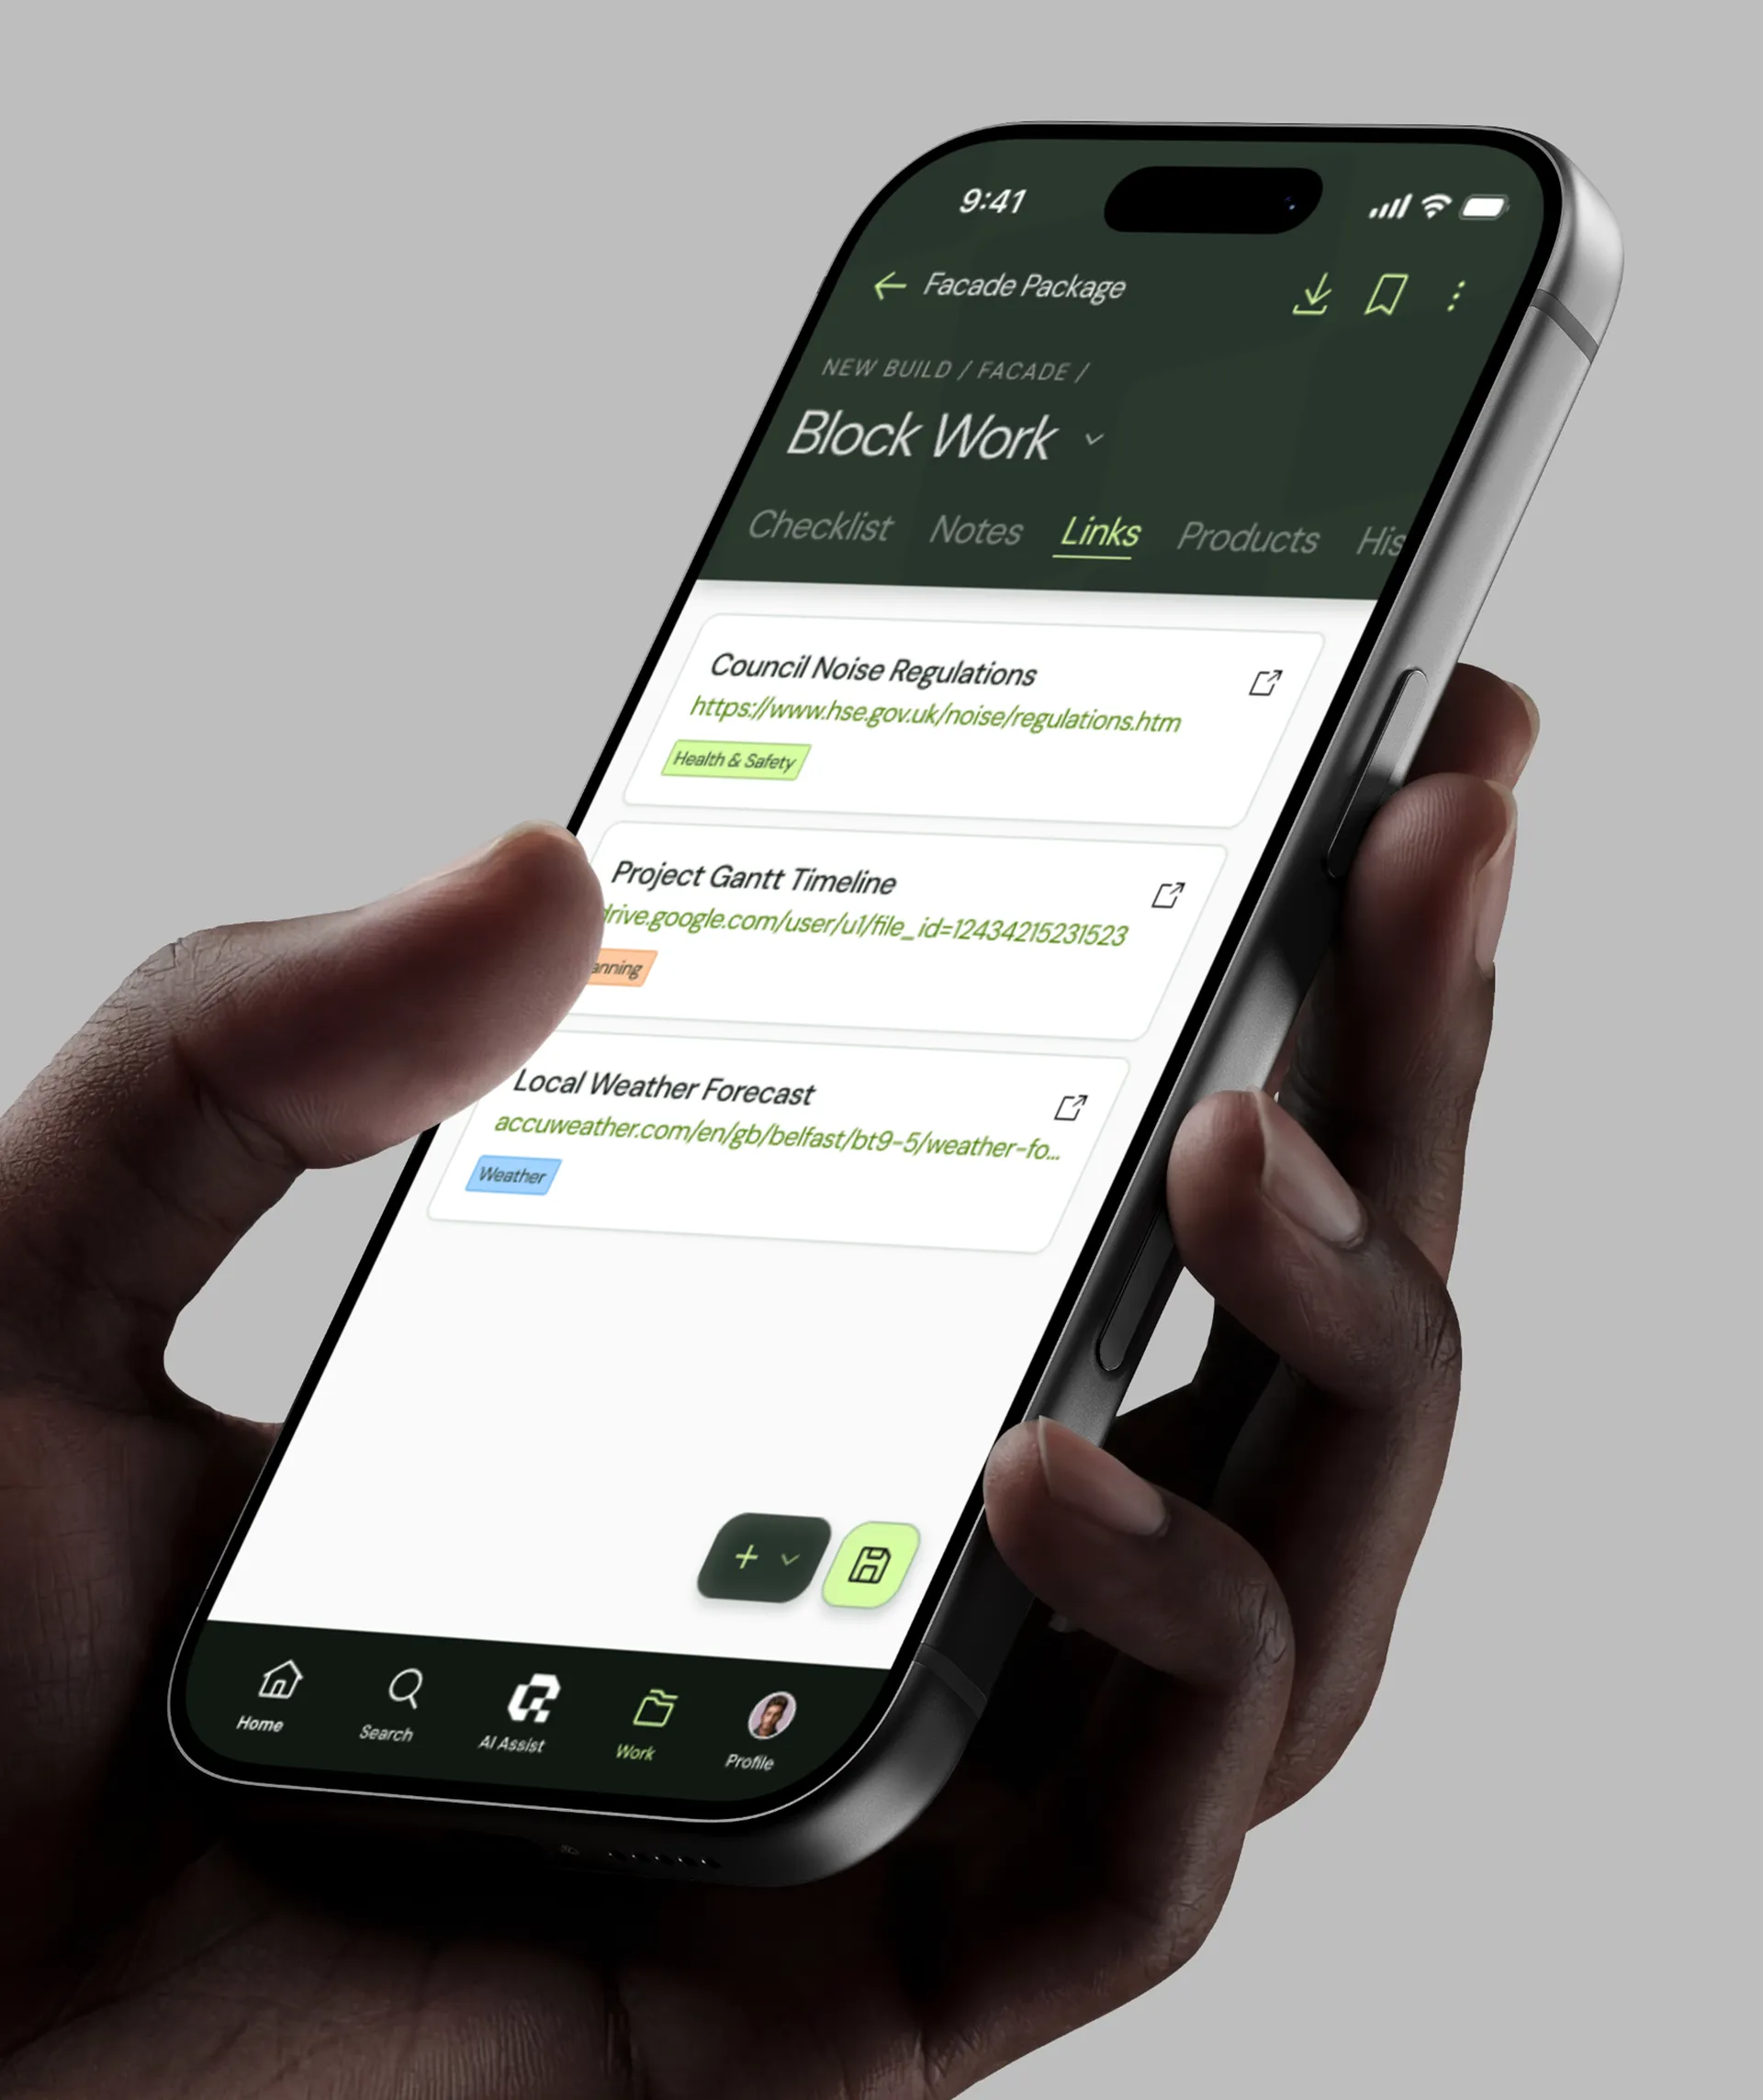
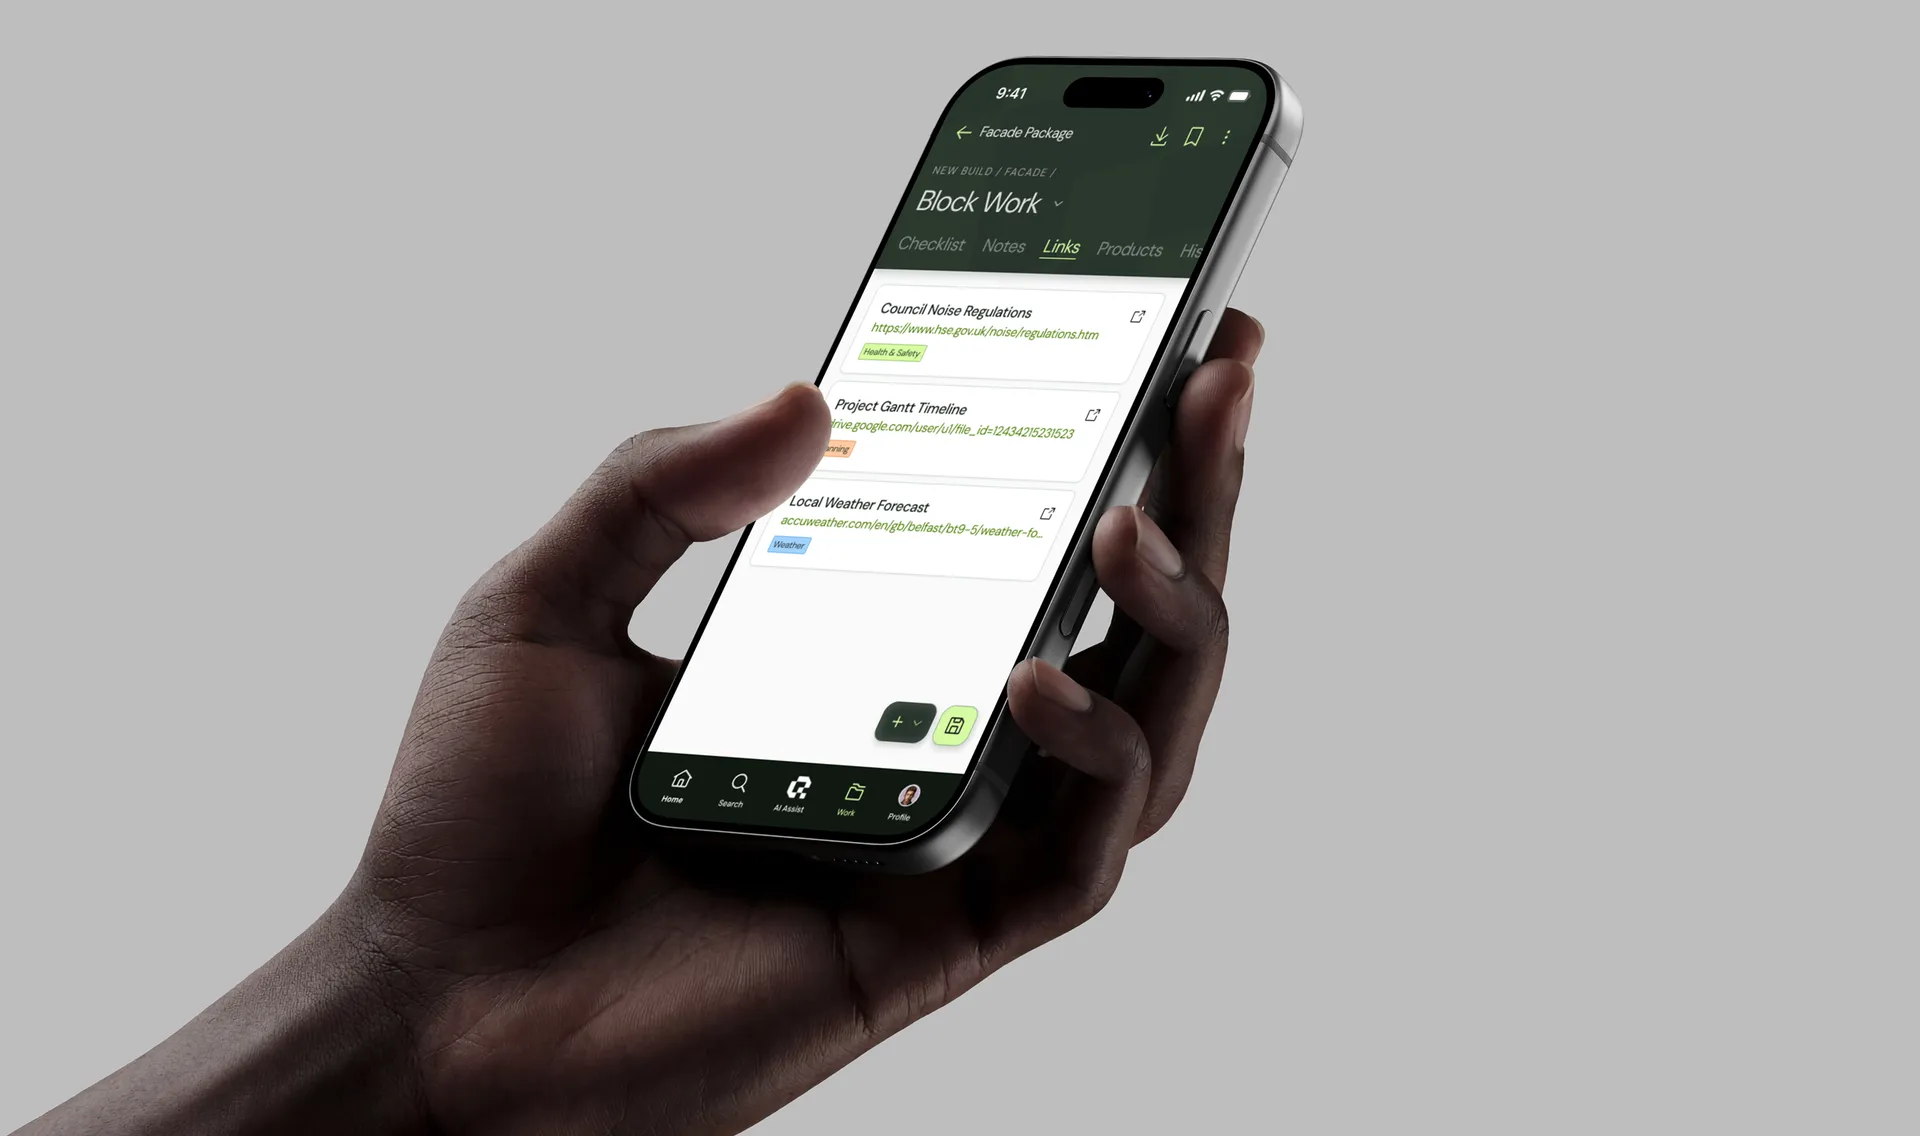
Phone showing a construction task checklist

Source Restriction via RAG

We restrict answers to your indexed documents, not the internet. New files are indexed as they're approved, keeping responses current. For one construction client this is what stops the assistant inventing safety guidance. The answer must be from the approved source.

Cited Sources in Every Answer
Two colleagues laughing at a desk

Cited Sources in Every Answer

Every response includes a source reference so your team can verify any claim in seconds.

Confidence Scoring and Thresholds
Framed posters on a white wall

Confidence Scoring and Thresholds

Each answer carries a confidence score. You set the threshold. Responses below it are flagged or withheld entirely, so uncertain outputs never reach end users.

Automated Fact-Checking
Hand holding a phone showing an assistant answer

Automated Fact-Checking

We cross-check outputs against your canonical records automatically. Contradictions are caught before the answer is served.

Human-in-the-Loop Verification
Four team members laughing at a meeting table

Human-in-the-Loop Verification

For high-stakes answers, flagged outputs go to a nominated reviewer before delivery. You keep final control over what your users see.

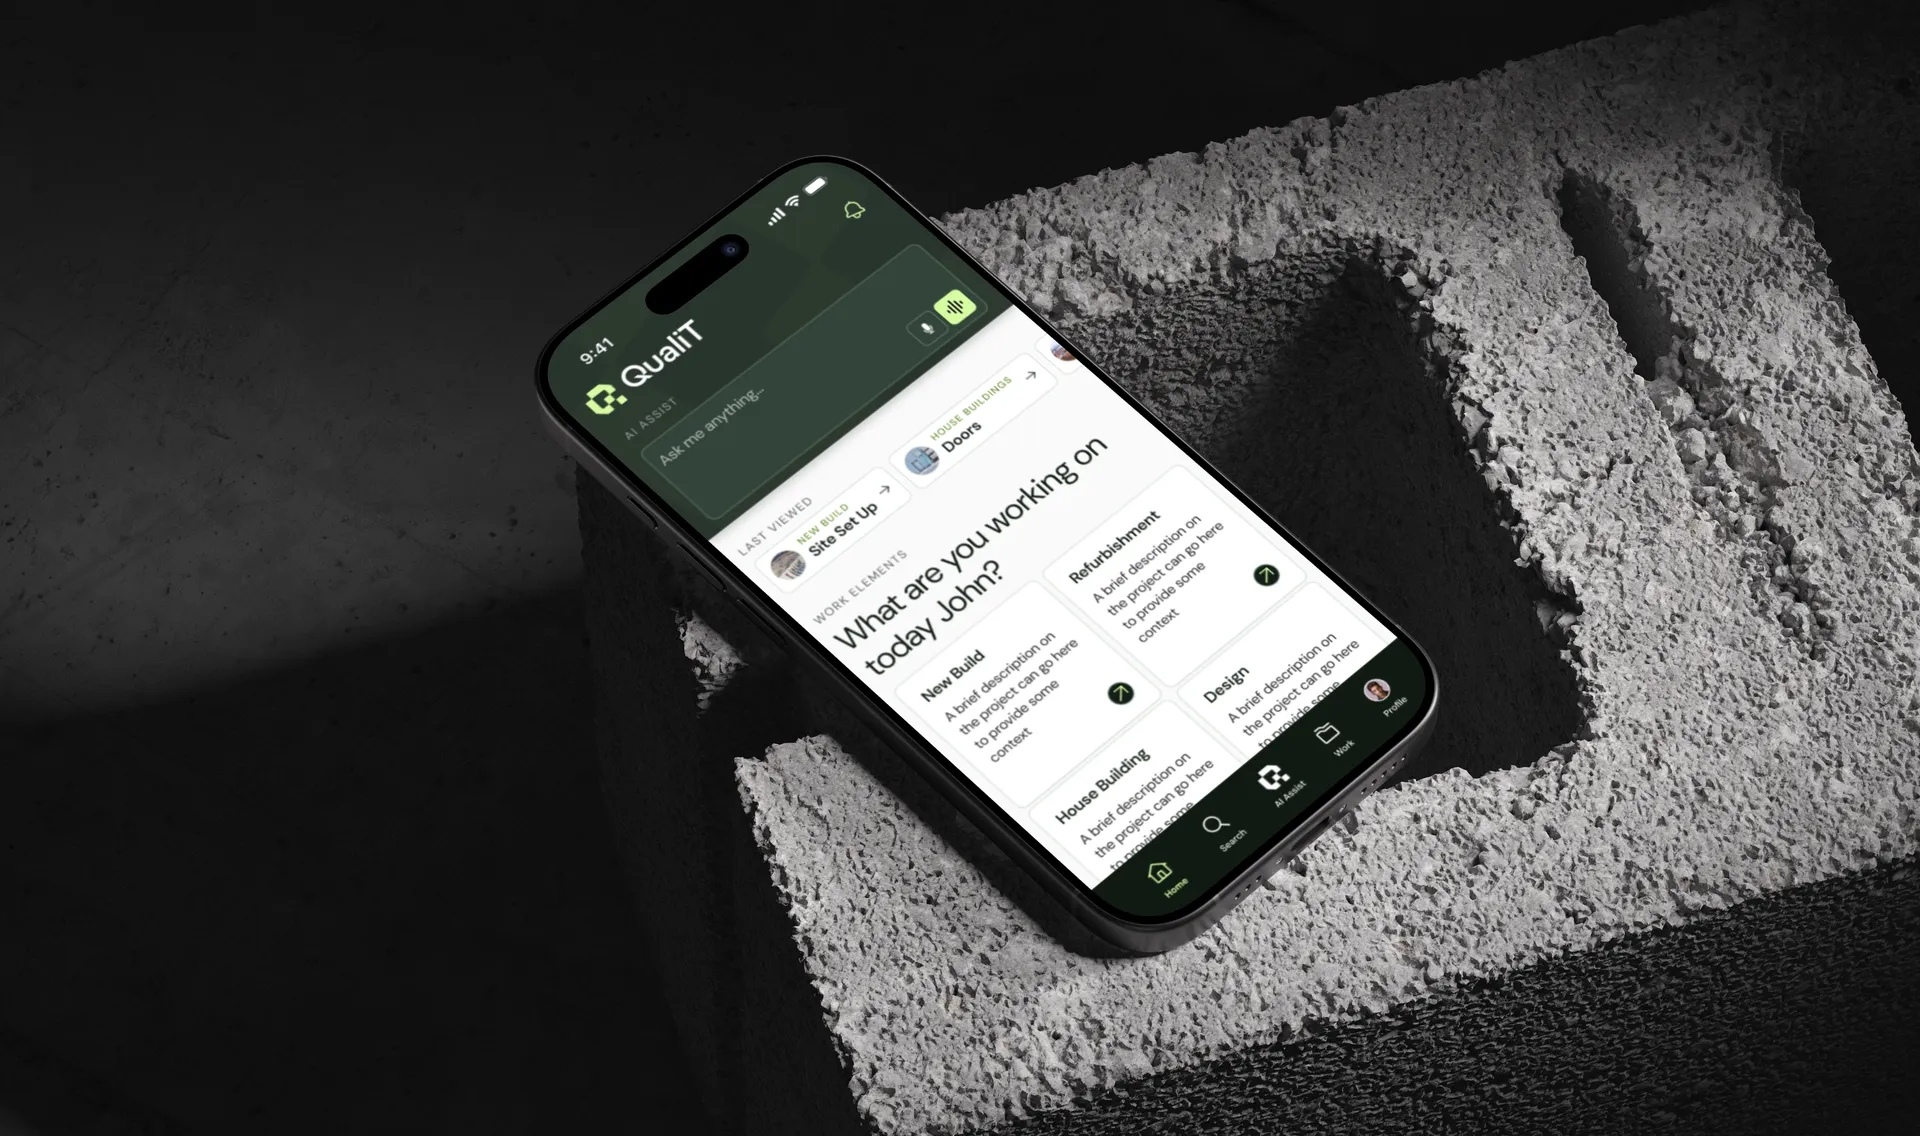
The QualiT app showing a construction work-package checklist on a phone

Live in construction: QualiT

We built a retrieval-augmented assistant that answers only from its approved construction checklists. Every response includes cited sources and a confidence score, so site teams trust the guidance without second-guessing.

  • Voice input for gloved workers
  • Declines when the answer is not in the approved documents
  • Cited sources on every answer
  • Confidence scoring flags uncertainty
AlphaVictor app Make it happen The North Face campaign AI development Newell Stores app Software development Juice Jar app App development MPS Data Discovery to deployment The Lir website In-house UK team

How does an LLM development project work?

We run every engagement in clear phases so you see progress and sign off at each milestone.

  1. Feasibility and Scoping

    We assess your data, define success metrics and recommend retrieval or fine-tuning before any build work starts.

  2. Data Preparation

    Your documents get cleaned, chunked and indexed. Chunking strategy matters: too large and retrieval loses precision, too small and the model loses context. We test different approaches against your actual queries to find the right balance.

  3. POC Build

    A working assistant on a subset of your data, tested against accuracy benchmarks. You see real answers, not slide decks.

  4. Evaluation and Iteration

    We measure hallucination rate, citation accuracy and confidence calibration. Low-confidence outputs get flagged for human review. This phase often reveals edge cases that reshape the retrieval logic.

  5. Production Deployment

    Secure hosting, API integration and monitoring with agreed service levels. The system goes live.

  6. Ongoing Support

    We update your index as documents change, apply model upgrades and provide regular performance reporting.

Myth Digital team at work in the studio Belfast office

Is LLM Development Right for You?

Not every project needs a custom language model. Use this checklist to see if yours is a fit.

A great fit

  • You have documents, policies or knowledge that staff or customers need to query
  • Accuracy and auditability matter. You need answers grounded in approved, citable sources
  • You want a UK-hosted or private deployment to meet data-residency requirements
  • You have a clear use case and a success metric your team can measure
  • Your team can name a focused starting point for a proof of concept

Not the right fit

  • You want a generic chatbot with no specific knowledge base behind it
  • You expect the model to replace human judgement in regulated decisions without oversight
  • You have no documents, records or data to ground the model on
  • You need a one-off content generator rather than a repeatable business tool
  • You are not ready to define what a good answer looks like for your users
Our track record

Building software since 2015

300+
Projects delivered
2 offices
In-house team, Belfast and London
100%
All work is in-house
  • Document-grounded assistants

    Retrieval systems that answer only from your approved content, returning cited sources so every response is verifiable.

  • Voice-input AI

    On-site workers speak questions instead of typing. Our assistants process voice input and return sourced, accurate answers.

  • Compliance-ready deployments

    Hosted on Microsoft Azure with UK data residency, encryption and strict access controls baked in from day one.

  • RAG pipelines

    We index your documents, build the retrieval layer and connect it to the model so answers stay grounded in your data.
  • Production monitoring

    Confidence scoring, automated checks and dashboards that flag low-quality outputs before they reach your users.

Myth Digital team at work in the studio

Your Data Stays in the UK

Yes, you can keep every document and query within UK borders. We deploy to UK-region Azure, private VPC-managed services or self-hosted open models on your own infrastructure. Encryption, role-based access and audit logging are in place from day one.

  • Private UK-region cloud hosting
  • VPC-based managed services with customer-managed keys
  • Self-hosted open models on your infrastructure
  • ICO obligations mapped during discovery

How much does LLM development cost?

Every project is different. These tiers reflect how most of our LLM engagements break down.

  • 2–4 weeks

    Viability & POC

    from £10,000

    Scope and data complexity drive the timeline.

    • Data assessment
    • Architecture recommendation
    • Working prototype on sample docs
    • Accuracy benchmarks
    • Production roadmap
  • 8–12 weeks

    Production Build

    from £25,000

    Based on past builds, a full production rollout usually lands in the mid-to-high five figures. Timeline depends on integrations and compliance work.

    • Full retrieval pipeline
    • System integration
    • Monitoring and SLAs
    • User interface
    • Team training
  • Rolling

    Ongoing Partnership

    from £2,000/mo

    Keep answers grounded as your documents and models change. We re-index new content, track accuracy against your benchmarks and tune the system every month.

    • Document re-indexing as content changes
    • Accuracy tracking against your benchmarks
    • Model upgrades and prompt tuning
    • Monitoring and SLAs
    • Monthly quality and usage report

All figures are indicative. We scope and quote after we understand your data, integrations and compliance needs.

Choosing the Right Model

There's no single best model. We recommend the provider that fits your data, compliance needs and budget, and we can switch later if requirements change.

  • Broad capability

    OpenAI / Azure OpenAI

    We have shipped production assistants on OpenAI, Anthropic and Azure AI services, and choose per project on capability, hosting region and cost. If you're already on Microsoft's cloud, it's the path of least resistance.

  • Safety & long context

    Anthropic Claude

    We reach for Claude when a project involves long documents or compliance-heavy workflows where cautious, careful outputs matter. Its large context window reduces the need to chunk aggressively.

  • Multimodal & media

    Google Gemini

    Handles text, image and video inputs natively. We'd recommend it for media-rich processes, though we'd host the surrounding infrastructure in the UK to maintain data residency.

FAQ

LLM development FAQs

What is LLM development?

It is the engineering that turns a large language model into a reliable business tool. Preparing your documents, building the retrieval layer that finds the right content, designing and testing prompts, evaluating answers, and deploying the service securely. Most businesses never need to train a model from scratch.

What is retrieval-augmented generation and when do we need it?

Retrieval-augmented generation searches your own documents at the moment a question is asked and gives the model only that content to answer from, with a citation back to the source. You need it whenever answers must come from your approved knowledge rather than the model's general training.

Should we fine-tune a model or use retrieval over our own documents?

Start with retrieval. It deploys faster, stays current as documents change, and shows its sources. Fine-tuning changes how a model behaves and suits narrow, high-volume cases. We recommend it only when the evidence from a retrieval pilot supports it.

How do you stop an LLM making things up?

We restrict answers to your indexed documents, attach a citation to every response, score confidence and decline when the answer is not in the approved sources. Low-confidence questions route to a person, and we test the assistant against known answers before and after launch.

Can an LLM be deployed privately for our UK data?

Yes. We can keep documents and queries within UK or EU regions on Microsoft Azure, use managed services with your own keys, or run open models on your own infrastructure. Encryption, role-based access and audit logging are in place from day one.

How much does LLM development cost?

A proof of concept over your own documents is a fixed-fee, two-to-four-week phase, and a production build is scoped from what it shows. The pricing tiers on this page give the starting points, and you receive a fixed proposal before the build begins.

How long does an LLM project take?

A proof of concept usually takes two to four weeks, including preparing and indexing a sample of your documents. A production assistant with integrations, evaluation and monitoring typically runs eight to twelve weeks.

Further reading

Guides and thinking from our team on AI strategy, automation and choosing the right approach.

Book a feasibility call

RAG or fine-tuning: which fits?